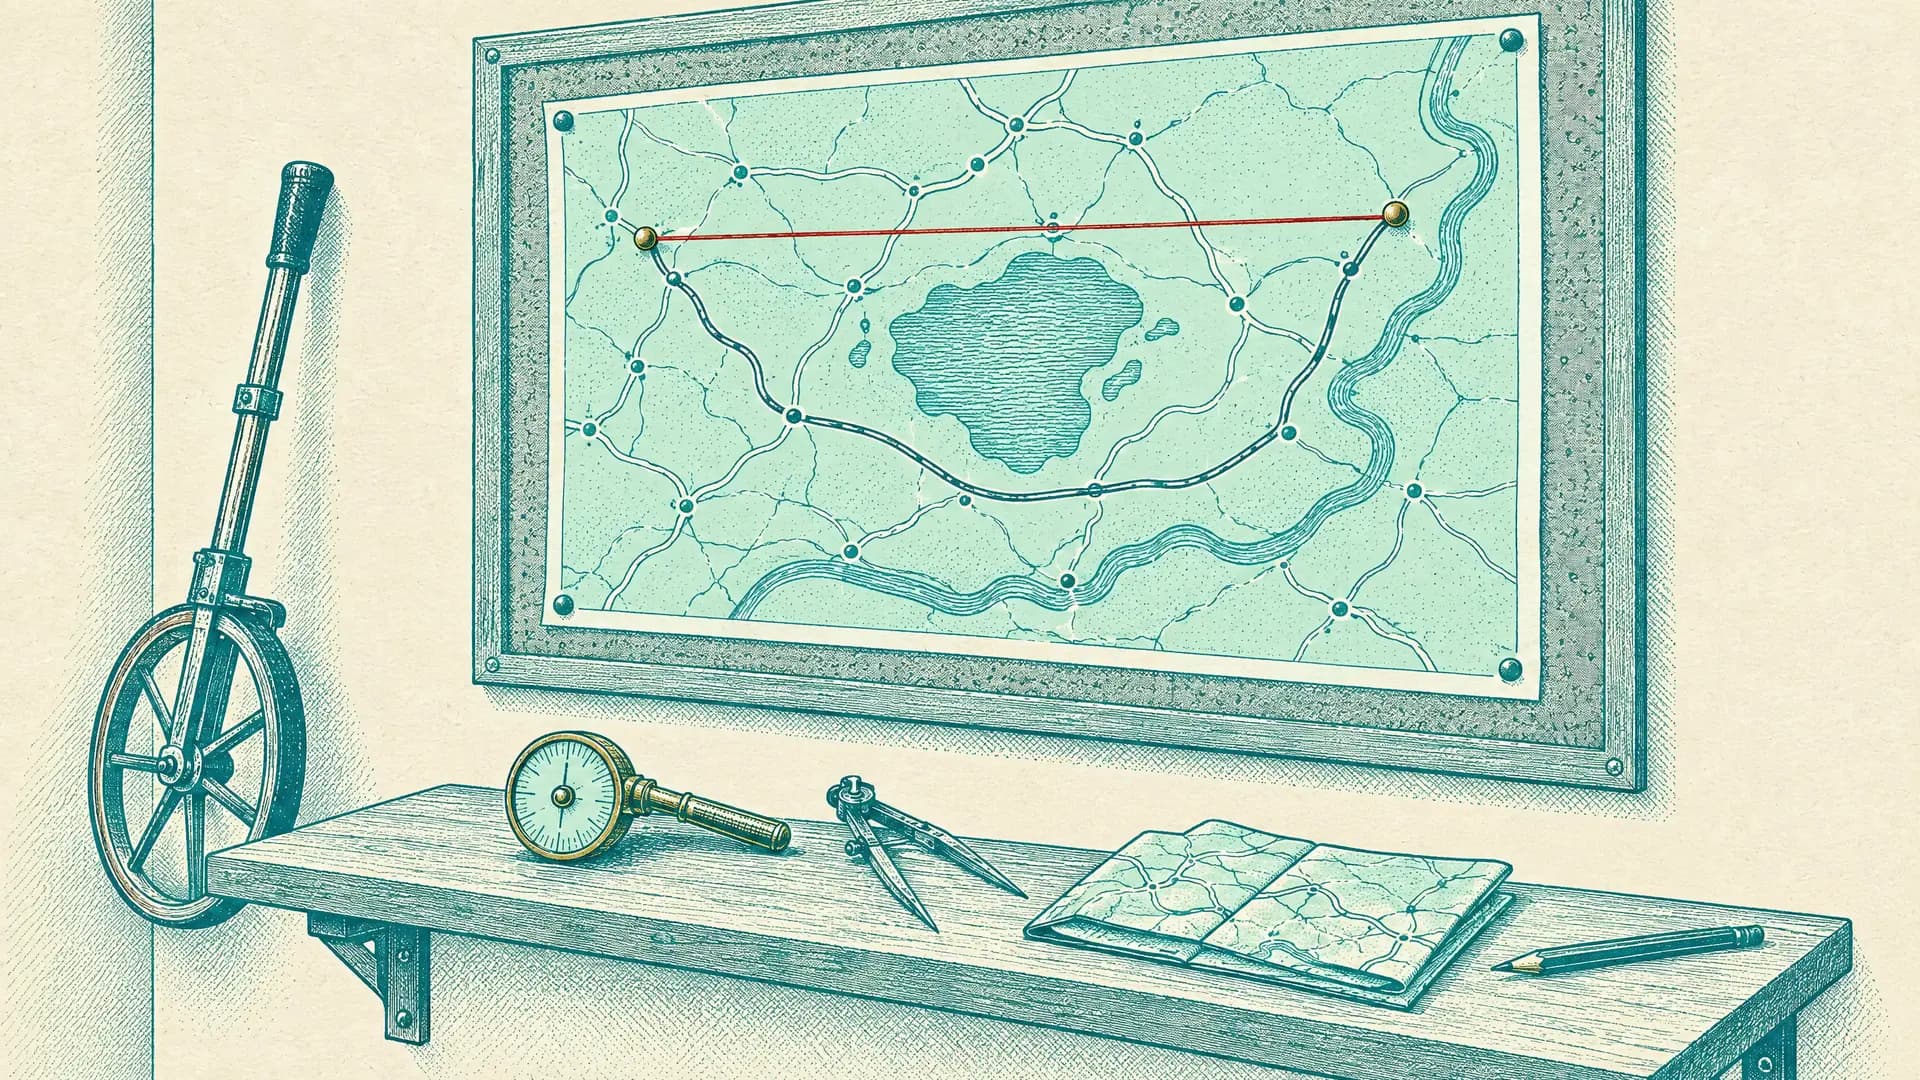
*A network model is only as good as the distances you feed it. The solver gets the credit. The distance matrix does the work.*
The cleverest optimiser in the world cannot repair a wrong distance.
Yet most network studies I have seen start from a spreadsheet of straight-line distances, or from a colleague’s memory of how long the lorry takes. The solver then grinds those numbers into a confident answer. The answer is exactly as reliable as the guess underneath it.
Ask a chatbot how far Antwerp is from Lyon by road and you get the same thing: an answer from memory, sometimes close, never checkable. That is not the model’s fault. Nobody gave it a map.
The map exists, and it comes as a set of APIs. One turns an address into coordinates. Another turns two lists of coordinates into a matrix of kilometres and hours, and a third draws the area a driver can reach before lunch.
This post is about those APIs, what they cost and where they trip you up. A test on the fictional Upshift network shows how much they change the answer.
What these APIs are
Four questions cover almost everything a network or distribution study asks the map. Each has its own family of services.
Where is it? Geocoding turns “Rue de Fer 12, 5000 Namur” into a latitude and longitude. Google, HERE and Mapbox sell it, Nominatim on OpenStreetMap gives it away, and OpenCage and Geoapify wrap open data into a supported service.
Several European registers are free and official: the Flemish address register, Belgium’s federal BeST files and the Dutch PDOK Locatieserver. The French Géoplateforme geocoder even takes a CSV of up to 200,000 lines in one upload.
How far, and how long? A matrix API takes a list of origins and a list of destinations and returns distance and time for every pair. Request limits differ a lot.
Google’s Routes API caps a matrix at 625 elements and Mapbox at 25 coordinates. HERE goes to 10,000 by 10,000 as a batch job, and PTV Developer takes 1,000 locations and adds tolls.
If you would rather own the engine, OSRM, Valhalla, GraphHopper and OpenRouteService are open source and run on OpenStreetMap data. A 5,000 by 20 matrix then costs a server, not a bill. In North America, Trimble’s PC*MILER describes itself as the industry standard for truck mileage.
Truck matters. Google’s TRUCK mode is limited to selected customers and covers the contiguous United States, so in Europe its matrix is a car matrix. HERE, TomTom, PTV, AWS, Azure and Valhalla take weight, height, axles and hazardous goods, and route around the bridges a 40-tonne lorry cannot use.
What can we reach in two hours? Isochrone APIs draw the area reachable from a site within a given time. HERE’s Isoline goes up to nine hours with a truck profile, Mapbox stops at 60 minutes, and OpenRouteService’s public API at one hour.
What else does the lane cost? HERE returns tolls per section for cars and trucks, and PTV forecasts future toll rises. Searoutes gives port-to-port sea distance and duration. EcoTransIT World and Climatiq turn a lane into CO2 under the GLEC Framework and ISO 14083, the 2023 standard for transport emissions.
Here are the ten I would shortlist for a network study, with the vendors’ list prices on 30 September 2026. HERE marks its page as indicative, and HERE and TomTom count matrix “transactions” with a formula that favours large matrices.
| API | What it gives a network study | Free band, then list price | Worth knowing | Source |
|---|---|---|---|---|
| Google Maps Platform | Geocoding, address validation, route matrix | 10,000 geocodes and 10,000 matrix elements a month, then $5 down to $0.38 per 1,000 | 625 elements a request; truck mode only for selected customers in the US; coordinates cached 30 days at most | Pricing |
| HERE | Geocoding, matrix up to 10,000 by 10,000, isolines, tolls | 30,000 geocodes and 2,500 matrix transactions a month, then €0.70 and €4.66 per 1,000 | Truck profiles with weight, height and hazardous goods; results kept 30 days at most | Pricing |
| Mapbox | Geocoding, matrix, isochrones, an MCP server | 100,000 geocodes and 100,000 matrix elements a month, then $0.75 and $2 per 1,000 | 25 coordinates a matrix request; cheap geocodes may not be stored, permanent ones cost $5 per 1,000 | Pricing |
| TomTom | Matrix routing with truck profiles, an MCP server | 2,500 matrix transactions a month, then €3 down to €1.95 per 1,000 | 100 elements a synchronous request, 2,500 as a batch job, 100 million on the enterprise tier | Pricing |
| PTV Developer | Truck matrix with toll costs on European road data | Free trial, then prices on request; none published on the pages I opened | 1,000 locations a request; toll prices only in the asynchronous mode | Docs |
| OpenCage | Geocoding on open data, results yours to keep | 2,500 requests a day on trial, then €45 to €900 a month for 10,000 to 300,000 a day | Attribution required; no matrix | Pricing |
| GraphHopper | Matrix and route optimisation, hosted or self-run | 500 credits a day free for non-commercial use, then €69 to €479 a month for 5,000 to 50,000 a day | A matrix costs origins times destinations divided by two credits; the engine is Apache 2.0 | Pricing |
| openrouteservice | Matrix and isochrones on OpenStreetMap | Free: 500 matrix requests a day, 3,500 elements each | Run your own instance for no limits | Restrictions |
| OSRM | The fastest self-hosted matrix | Free under the BSD licence; you pay for the server | Car, bicycle and foot profiles; 100 locations a table by default, configurable | Docs |
| Valhalla | Self-hosted matrix with truck costing | Free under the MIT licence; you pay for the server | Respects height, width, weight and hazardous-goods restrictions | Docs |
Not in the ten, but free and official: Nominatim, at one request a second and no bulk runs, and the Belgian, Dutch and French address registers above.
What it means for supply chain
I think of distance data as a ladder. Every rung costs more than the one below, and most questions have a rung that is good enough.
| Rung | What you measure | Where it comes from | Good enough for |
|---|---|---|---|
| 1 | Straight line | A formula in the spreadsheet | A first centre-of-gravity sketch |
| 2 | Straight line times a circuity factor | The same formula and one constant per country | Screening candidate regions |
| 3 | Road distance, car profile | A matrix API, or your own OSRM | Allocating customers to hubs, cost-to-serve |
| 4 | Road distance and time, truck profile | HERE, TomTom, PTV, Valhalla | Lane costing, tender benchmarks, service promises |
| 5 | Plus tolls, ferries, driver hours and CO2 | Toll, sea-route and emission APIs | Route design, lane cost, ISO 14083 reporting |
The circuity factor on rung 2 has a literature. Ballou’s 2002 country factors, as reported in an MIT lecture, put Germany at 1.32, Poland at 1.21 and France at 1.65. A 2012 study of 66,000 US locations found roads 1.417 times longer than the straight line.
Where the rungs land in practice:
- Greenfield and the sixth hub. Rung 2 screens candidate regions across thousands of customers for free, and rung 3 confirms the shortlist.
- Allocating customers to hubs. Rung 3 is the minimum. Straight lines misallocate anyone near a coast, a mountain range or a ferry.
- Lane benchmarks for the transport tender. Rung 4 gives the kilometres a carrier will actually drive, so a rate per kilometre means something.
- Service promises by drive time. Isochrones show which postcodes a hub can reach next day, before you promise it.
- CO2 per lane. ISO 14083 reporting needs a distance per leg and per mode, and a matrix per mode is the raw material.
- A map for your AI agent. Mapbox and TomTom publish MCP servers with geocoding, matrix and isochrone tools, so an assistant can measure instead of guess.
The Upshift scenario list has a question that touches all of this: should the company open a sixth hub in Vienna? Let’s climb the ladder with it.
Worked example: does a Vienna hub pay off?
Upshift, the fictional bicycle maker behind this site, ships from five hubs (Venlo, Kassel, Lyon, Northampton and Basel) to 52 customers in nine countries. I ran the study on 30 September 2026 with two free services: Nominatim for geocoding and the public OSRM demo server for road distances. The numbers are real outputs on that small dataset, unweighted per customer, and you can rerun them from the [Upshift dataset](/dataset).
Step 1: geocode the file as it is. Fifty-two rows went in and ten came back empty. Three had a city in the wrong country: Stuttgart filed under Switzerland, Bordeaux under Germany, Utrecht under “Deutschland”. Seven were British rows with “UK” instead of “GB”, or a postcode district like M1 instead of a full postcode.
The other 42 resolved, all at city level, because the file has no street. That is the first result of any geocoding run: a list of rows you must fix by hand.
Step 2: screen with a straight line. With the countries corrected, a haversine formula gave the crow-flies distance from every customer to every hub. Multiplied by a circuity factor, that approximates road. Across my own matrix the median factor came out at 1.28, between Ballou’s Poland and Germany.
Step 3: ask for one matrix. Eight sites (two plants, five hubs and the Vienna candidate) by 30 distinct customer towns is 240 elements. OSRM returned distance and drive time for all of them in one call, in under a second. On Google that is 240 elements and on HERE or TomTom 150 transactions, all inside the free bands.
Step 4: compare the rungs. Allocate each customer to the nearest hub by straight line, then measure the result by road: 389 km per customer on average. Allocate by road instead: 347 km, twelve per cent less. Four customers flip.
Paris sits 392 km from Venlo and 393 km from Lyon as the crow flies, but 476 km and 463 km by road.
Three customers in Bergen look closest to Northampton on a globe, 984 km away. By road they are closest to Kassel, 1,836 km and 23 hours later. Nobody drives a bike delivery for 23 hours, so the real lane is a short-sea crossing, and the matrix showed exactly where the road stops being the right question.
Step 5: answer the Vienna question. Add the sixth hub and three customers move to it: Vienna itself, Graz and Warsaw. The average falls from 347 km to 316 km, and total delivery kilometres from 18,056 to 16,424, a nine per cent saving before anyone has priced the building. Both rungs agreed on which customers move.
Step 6: hand the AI the matrix, not the question. I let an assistant write the script and the summary, with one rule: every kilometre comes from the matrix. Its own memory of European geography stays out of the model.
Notice two things. The rung-2 screen was good enough for the strategic question, and the rung-3 matrix was needed to get the allocation right. And the twelve per cent error from allocating by straight line is bigger than the nine per cent the new hub saves. When the distances are wrong, the optimiser is optimising noise.
What it can’t do, and the traps
- Read the licence before you store anything. Google and HERE let you cache coordinates for 30 days, and Mapbox’s cheaper “temporary” geocodes may not be cached at all. OpenCage, Geoapify and the public registers let you keep results, with attribution.
- Public demos are not batch tools. Nominatim’s policy is one request per second, an identifying user agent and no bulk geocoding. For a real customer file use a paid tier, a national register or your own server.
- A car matrix is not a truck matrix. Rung 3 ignores bridges, tunnels and weight limits. Use a truck profile before you turn kilometres into lane rates.
- Road distance is not lane cost. Tolls, ferries, driver hours and empty returns sit on top, and Bergen showed how a road answer can be the wrong mode entirely.
- Customer addresses can be personal data. The GDPR names location data as an identifier and a home address as personal data. Pseudonymise consumer files before they leave your systems, and check where the vendor processes them.
- APIs move. Google’s Distance Matrix API is now marked legacy, the old French address API was scheduled for decommissioning in January 2026, and HERE has deprecated its truck parameters. Keep the provider name and the date next to every stored coordinate.
Geocode your customer file this week
Take the 200 customers with the most deliveries, run them through a national register or a free tier, and plot the dots. Count the rows that fail, and count the dots that land in the wrong country. That hour tells you more about your network data than a month with a solver.
Supply chain people have always known that the map matters. The difference now is that the map answers in seconds, for cents, and that your AI can call it too.
Which rung is your current network study standing on?
Sources
- Google Maps Platform, pricing
- Google Maps Platform, service specific terms (caching rules)
- Google Geocoding API, requests and location types
- Google Routes API, compute a route matrix
- Google Routes API, large vehicle routing
- Google Distance Matrix API, usage and billing (legacy)
- Mapbox Geocoding API, temporary and permanent results
- Mapbox Matrix API
- Mapbox, pricing
- Mapbox MCP server on GitHub
- HERE, pricing
- HERE platform terms, September 2023
- HERE Matrix Routing API v8, matrix modes and sizes
- HERE Matrix Routing API v8, truck parameters
- HERE Isoline Routing API v8
- HERE Routing API v8, tolls
- TomTom Matrix Routing API v2, synchronous matrix
- TomTom, pricing
- TomTom Maps MCP server on GitHub
- PTV Developer, Matrix Routing API
- OpenStreetMap Foundation, Nominatim usage policy
- OSRM API documentation, table service
- Valhalla, time-distance matrix service
- Valhalla, route API reference (truck costing)
- GraphHopper, pricing
- openrouteservice, API restrictions
- Trimble Maps, PC*MILER
- AWS Location Service, CalculateRouteMatrix
- Azure Maps, Route Matrix
- Basisregisters Vlaanderen, API limits
- BOSA, BeST Address open data
- PDOK Locatieserver
- Géoplateforme, geocoding guide and CSV batch
- API Adresse, deprecation notice
- OpenCage, pricing
- Geoapify, pricing
- Searoutes, developer documentation
- EcoTransIT World, emission calculator and API
- Climatiq, intermodal freight API
- BSI, ISO 14083 greenhouse gas emissions from transport chain operations
- MIT CTL.SC1x, One to many distribution, circuity factors after Ballou (2002)
- Boscoe, Henry and Zdeb (2012), driving distance versus straight-line distance
- GDPR, Article 4, definitions